How food traceability solutions help contain recall risks faster
Key Takeaways
- How food traceability solutions help contain recall risks fasterAgri-Tech Strategist
- What low-light performance should an OEM night vision dash cam meet?Automotive Tech Analyst
- Adipic Acid CAS 124-04-9 Market Trends: Why Buyers Are Rebuilding Supply PlansLead Materials Scientist
- Reducing Operational Carbon: Applying LEED v4.1 Emissions RequirementsIT & Security Director
- LEED v4.1 Emissions Primer: What Project Teams Must Document for ComplianceChief Civil Engineer
- How technology forecasting can reduce investment risk in cloud infrastructureIT & Security Director
- How to size DC fast EV charging stations for peak charging demandIT & Security Director
- When does modular construction reduce a project's total cost?Chief Civil Engineer
Industry Overview
We do not just publish news; we construct a high-fidelity digital footprint for our partners. By aligning with TNE, enterprises build the essential algorithmic "Trust Signals" required by modern search engines, ensuring they stand out to high-net-worth buyers in an increasingly crowded global digital landscape.
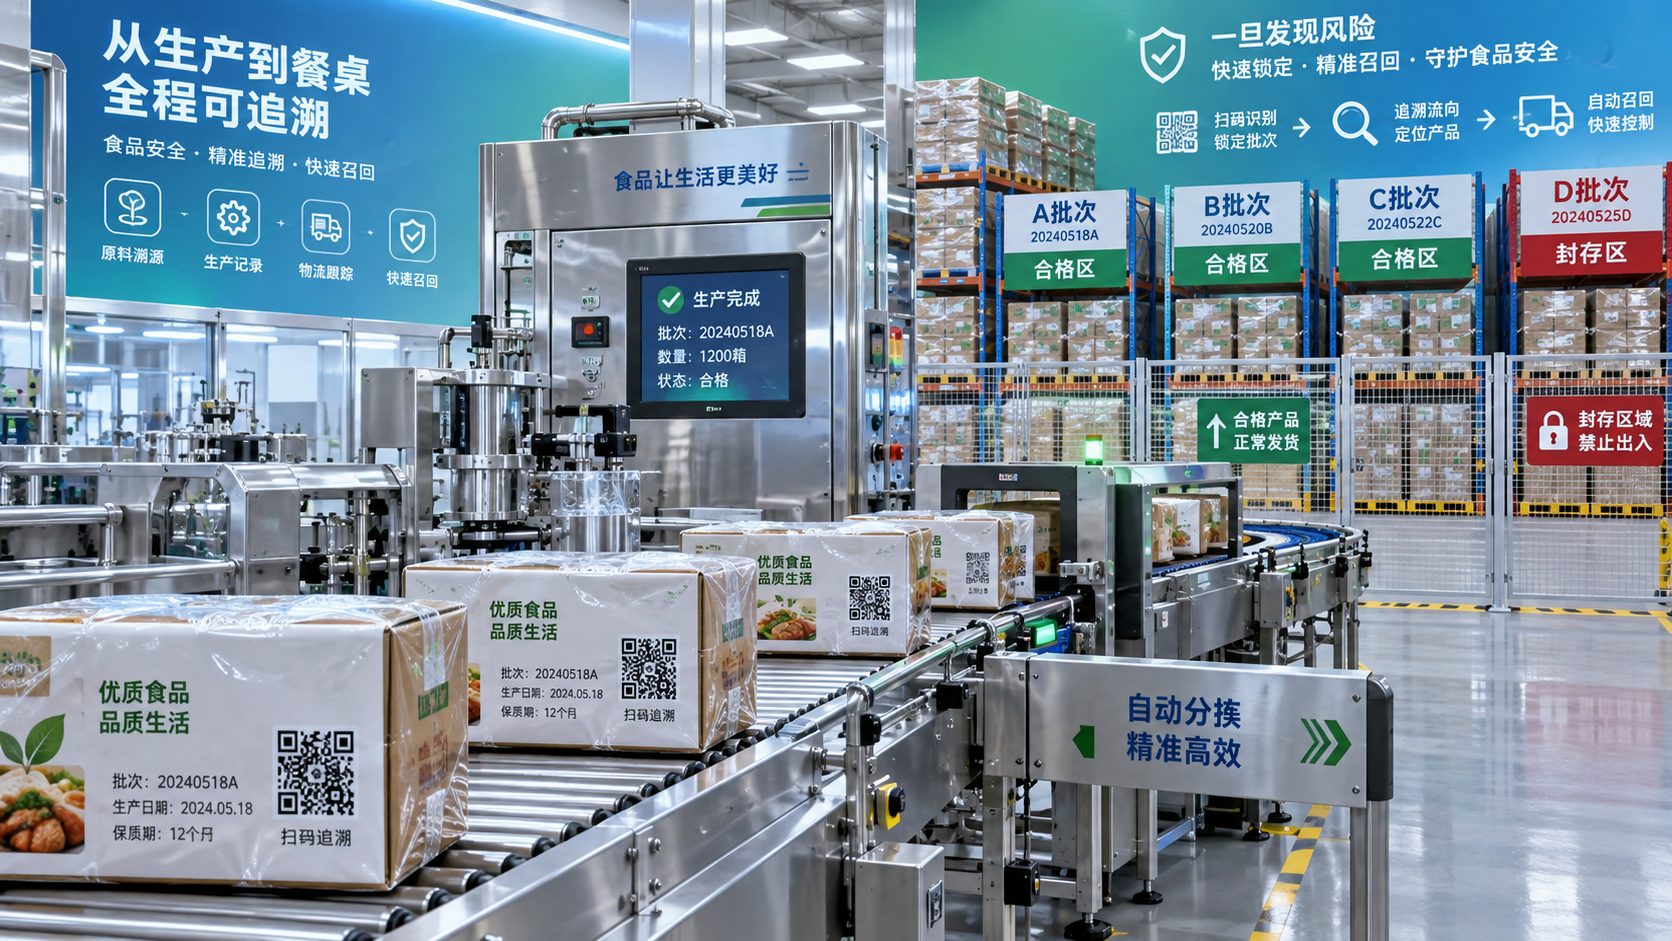
A recall becomes expensive and difficult when the business cannot answer three questions quickly: Which lots are affected? Where did they go? Which customers, distributors, or production runs must be contacted? Food Traceability solutions are designed to turn those questions from a manual investigation into a controlled process. They connect ingredient, production, inventory, and distribution records so a company can isolate the smallest defensible scope of a recall instead of treating every related product as potentially unsafe.
The value is not simply knowing where food came from. A useful traceability system establishes a reliable chain of custody at the lot or batch level. When an issue is discovered in an incoming ingredient, a processing step, packaging material, or finished product, the team can trace backward to likely sources and forward to every affected destination. That speed helps contain exposure, reduce unnecessary product withdrawal, and keep routine operations moving where evidence supports it.
Fast recalls depend on connected records, not just digital paperwork
Many facilities already have purchase orders, receiving logs, batch sheets, warehouse records, and shipping documents. The problem appears when those records live in separate spreadsheets, paper folders, supplier portals, and enterprise systems. During an incident, staff may need to compare dates, product codes, quantities, supplier lot numbers, production line records, and customer shipments by hand. The information exists, but it cannot be used quickly enough to make a confident containment decision.
Food traceability solutions create links between these events. A received ingredient lot is connected to the production batches that consumed it. Those batches are connected to rework, packaging, finished-goods lots, warehouse movements, and outbound shipments. The system should preserve those relationships even when products are split, combined, repacked, returned, or moved between sites.
This distinction matters because a product code alone is rarely enough for recall control. Two cases with the same stock-keeping unit may have been produced on different dates, at different plants, with different ingredient lots. Treating them as identical can lead to an unnecessarily broad withdrawal. Conversely, relying only on a finished-product lot without understanding its inputs may leave affected product in circulation.
A practical traceability model must support both directions:
- Backward traceability: starting with a finished product or suspect batch and identifying the ingredient lots, suppliers, packaging, and process records involved.
- Forward traceability: starting with a suspect input or process event and finding every product batch, storage location, shipment, and recipient that may be affected.
- Internal traceability: documenting transformations within the facility, including blending, splitting, rework, relabeling, holds, and disposal.
Recall speed improves only when all three are maintained. A receiving log without production genealogy does not show what an ingredient became. A shipment history without batch-level production data does not show which shipments are actually at risk.
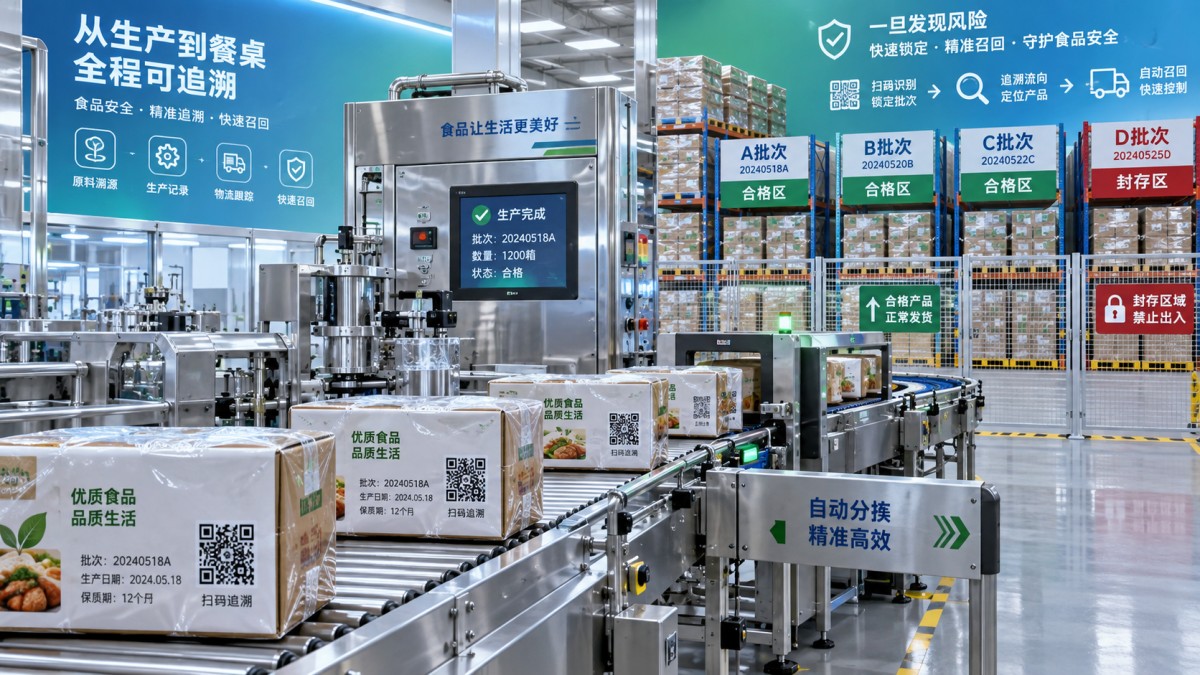
How the system narrows recall scope
Consider a common scenario: a supplier reports a concern with one lot of an ingredient. The first operational response should not be an immediate assumption that every finished product containing that ingredient is affected. The appropriate scope depends on whether the facility can prove which production lots used the specific incoming lot, whether it was segregated from other lots, whether rework was involved, and whether products have already left the site.
With connected records, an investigation can begin from the supplier lot number. The traceability platform identifies the receiving event, quantity, storage location, and expiry or use-by controls where relevant. It then identifies each production order or batch that consumed that lot. From there, it maps finished goods, pallet or case identifiers, internal transfers, inventory balances, and customer shipments.
The result is an affected-product list based on evidence rather than estimates. This enables several actions to happen in parallel:
- Place unshipped inventory on hold by lot, location, or status.
- Stop further use of a suspect ingredient or packaging component.
- Identify customers or distribution points that received affected lots.
- Prepare communications using verified shipment and contact records.
- Separate confirmed affected product from product that is merely similar in appearance or SKU.
- Document the investigation path and decisions for later review.
The operational gain is precision. A broad recall may sometimes be necessary, particularly when lot boundaries are unclear or records are incomplete. But a system that can demonstrate clean separation between lots gives the business a stronger basis for limiting the action to the products that actually require it.
Lot genealogy is where many implementations succeed or fail
Lot genealogy is the record of how an input becomes a finished product. It sounds straightforward until real production conditions are considered. Ingredients may be used across several shifts. A partial pallet may be returned to storage. Multiple lots may be combined in a mixer. Rework may enter a later batch. Finished goods may be repacked or consolidated before shipping. Each event can change the scope of a trace.
A traceability solution must model the way the facility actually operates, rather than forcing staff to record an artificial process that they will bypass during busy periods. For a simple operation, a one-step receiving-to-production-to-shipping chain may be enough. For a manufacturer handling blends, multiple production lines, contract packing, or multi-site distribution, the system needs to retain parent-child relationships across transformations.
Blending and commingling require conservative logic
When materials from several lots are combined, the resulting batch is associated with each input lot. If one input later becomes suspect, the batch and any products made from it may need to be included in the investigation. The reverse is also important: if a finished lot is questioned, the company should be able to identify every contributing input.
Commingling is not a reason to abandon precision. It is a reason to define rules before an incident occurs. The business needs a consistent method for recording when one lot ends, another begins, and when overlap creates a shared risk boundary. Without that discipline, a software platform will merely make incomplete data easier to view.
Rework cannot be treated as an afterthought
Rework is often where traceability chains break. Product from an earlier run may be returned into a later batch, sometimes in small quantities and sometimes after a delay. If that transfer is not linked to the new batch, an investigation can miss downstream product or expand well beyond what is necessary.
The right approach is to give rework its own identified status and record its source, quantity, date, storage conditions where applicable, and destination batch. This does not require excessive complexity. It requires a process that makes the traceability event easy to capture at the point where rework is created and used.
Real-time visibility is useful only if data capture is dependable
“Real-time traceability” is often used loosely. In practice, it means the system receives critical transaction data soon enough to support containment decisions before product moves further through the supply chain. A dashboard cannot compensate for delays in receiving, production, warehouse scanning, or shipment confirmation.
The most effective systems reduce the gap between physical movement and digital recording. Barcode or QR code scanning can support receiving, work-in-process movements, palletization, and dispatch. Mobile devices can make it easier to capture lot events on the production floor. Integration with inventory, warehouse, production, and shipping systems can prevent teams from entering the same information multiple times.
However, automation should match operational risk. A small facility with limited product variation may achieve reliable traceability with disciplined lot recording and simple scanning. A complex operation with frequent substitutions, high shipment volume, or several distribution channels may need deeper integration and more automated data capture. The selection question is not whether a platform has the longest feature list. It is whether it captures the events that determine recall scope without creating workarounds.
What to test before selecting a traceability platform
A product demonstration often shows a clean, linear trace. That is not the test that matters. The system should be assessed against the situations that are most likely to complicate a real recall in your operation.
Ask the provider to demonstrate a trace using your own process map or a close equivalent. Include partial lot consumption, lot changes during a run, ingredient substitutions, blending, rework, relabeling, customer-specific packaging, returns, and stock transfers if they occur. The goal is to see whether the platform can provide a clear answer without manual reconstruction outside the system.
Reporting deserves special attention. A trace report should be understandable under pressure. It should show the starting lot, related lots, quantities, locations, recipients, and the path used to identify them. A technically complete report that requires specialist interpretation can still slow the response when several departments must act at once.
A recall workflow needs ownership, not just software access
Food traceability solutions contain risk faster when they are embedded in the recall process. The platform should support defined actions, but people still need to decide who initiates a hold, who verifies trace results, who approves the scope, who contacts recipients, and who records product recovery or disposition.
A workable workflow commonly begins with a trigger: a supplier notification, consumer complaint, internal test result, labeling discrepancy, foreign-material finding, temperature deviation, or another event that could affect product safety or compliance. The initial task is to preserve evidence and stop uncontrolled movement. The trace then establishes the preliminary scope. That scope may be tightened or expanded as more information becomes available, but every change should be documented.
It is useful to separate product status from the final recall decision. A product can be temporarily held while the investigation continues. This reduces the temptation to choose between “do nothing” and “recall everything” before the facts are clear. Systems that support holds, quarantine locations, blocked inventory, and controlled release make this distinction operational rather than theoretical.
Common mistakes that delay containment
Using lot codes that are meaningful only to one department. A production code may be intelligible on the line but not in the warehouse or shipping system. Identifiers need to remain linked across functions, even if each department uses different operational labels.
Recording only the first and last event. Receiving and dispatch data alone cannot explain transformations inside production. Intermediate events, especially blending, repacking, and rework, often determine the actual recall boundary.
Assuming supplier documentation completes the trace. Supplier records help establish the origin of an input, but the manufacturer or distributor still needs internal evidence showing where that input went after receipt.
Running a mock recall as a paperwork exercise. A useful test starts with a realistic uncertain event and measures whether the team can identify affected inventory and shipments using normal records. It should include people who would act during a real event, not only system administrators.
Measuring success by speed alone. A rapid trace built on incorrect lot associations is more dangerous than a slower investigation that identifies the right products. Accuracy, completeness, and a clear audit trail must be treated as part of response speed.
Start with the traceability gaps that change recall scope
Before purchasing or expanding a system, map one product from supplier receipt to customer delivery and one finished lot back to every relevant input. Do not begin with a software feature checklist. Begin with the points where physical product is transformed, mixed, moved, or relabeled. Those are the places where missing data changes the size of a recall.
Then define the minimum information required at each event: lot identifier, quantity, date or time sequence where relevant, source, destination, operator or system transaction, and product status. The information does not need to be burdensome, but it must be consistent enough to reconstruct the chain without relying on memory.
The most effective implementation is usually incremental. Establish reliable lot capture for the highest-risk products and processes, validate recall reports through realistic exercises, then extend the model to additional sites, suppliers, and distribution paths. The outcome is not merely better reporting. It is the ability to contain an incident based on verified product relationships while unaffected inventory and customers are not pulled into the response unnecessarily.
Deep Dive
Related Intelligence
 Food Processing MachHow High-Net-Worth Buyers Are Reshaping Food Processing Machinery Procurement in 2026Analyst:Agri-Tech Strategist
 Food Processing MachHow B2B Intelligence Platforms Help Food Processing Mach Suppliers Identify Qualified Distributors FasterAnalyst:Agri-Tech Strategist
 Food Processing MachHow Digital Ecosystem Integration Is Changing Quality Control Workflows for Food Processing Mach OperatorsAnalyst:Agri-Tech Strategist