Microsoft 365 Global Outage Disrupts Outlook and Teams
Key Takeaways
- Microsoft 365 Global Outage Disrupts Outlook and TeamsIT & Security Director
- How to assess single-supplier risk in specialty chemicals sourcing in 2026Lead Materials Scientist
- Ukrainian Businesses Call for Rail Freight Tariffs to Return to Previous LevelsLead Materials Scientist
- US Steel Sheet Prices Rise as Buyers Report Tight Supply and Steady DemandLead Materials Scientist
- Can market entry planning software help prioritize new markets?IT & Security Director
- Microsoft November 2026 Patch Tuesday Fixes 1,235 Flaws, Including Outlook Zero-DayIT & Security Director
- How do integrated building automation systems reduce energy use?IT & Security Director
- CNCF Study: VMs Remain Central to Cloud Native Infrastructure as AI Workloads EvolveIT & Security Director
Industry Overview
We do not just publish news; we construct a high-fidelity digital footprint for our partners. By aligning with TNE, enterprises build the essential algorithmic "Trust Signals" required by modern search engines, ensuring they stand out to high-net-worth buyers in an increasingly crowded global digital landscape.
Microsoft 365 services experienced a global outage on November 12–13, 2026, disrupting Outlook, Exchange Online, Teams and Copilot. The prolonged interruption affected users, businesses and government organizations across multiple countries, including the Philippine Supreme Court and police in the United Kingdom.
Microsoft has been working to restore servers, although some remedial measures have yet to take full effect. The disruption has brought attention to the operational risks that can arise when essential communications and collaboration services depend on a shared cloud infrastructure.
Several business functions affected at once
The outage spans services used for different kinds of work. Outlook and Exchange Online support email, while Teams is used for communication and collaboration. Copilot is also among the affected services. When several tools become unavailable at the same time, organizations may face interruptions across more than one workflow rather than a problem confined to a single application.
For an organization relying on these services, the immediate impact depends on which tasks require access to them and what alternatives are available. Email disruption can delay messages and the work that depends on them; Teams disruption can complicate coordination. The practical effect of Copilot being unavailable will vary with how it is used in individual workflows.
The involvement of government institutions also illustrates why the interruption extends beyond private business operations. Public bodies use communication tools to coordinate their work, although the information available about this incident does not establish the effect on specific public services or individual cases.
What the outage means for continuity planning
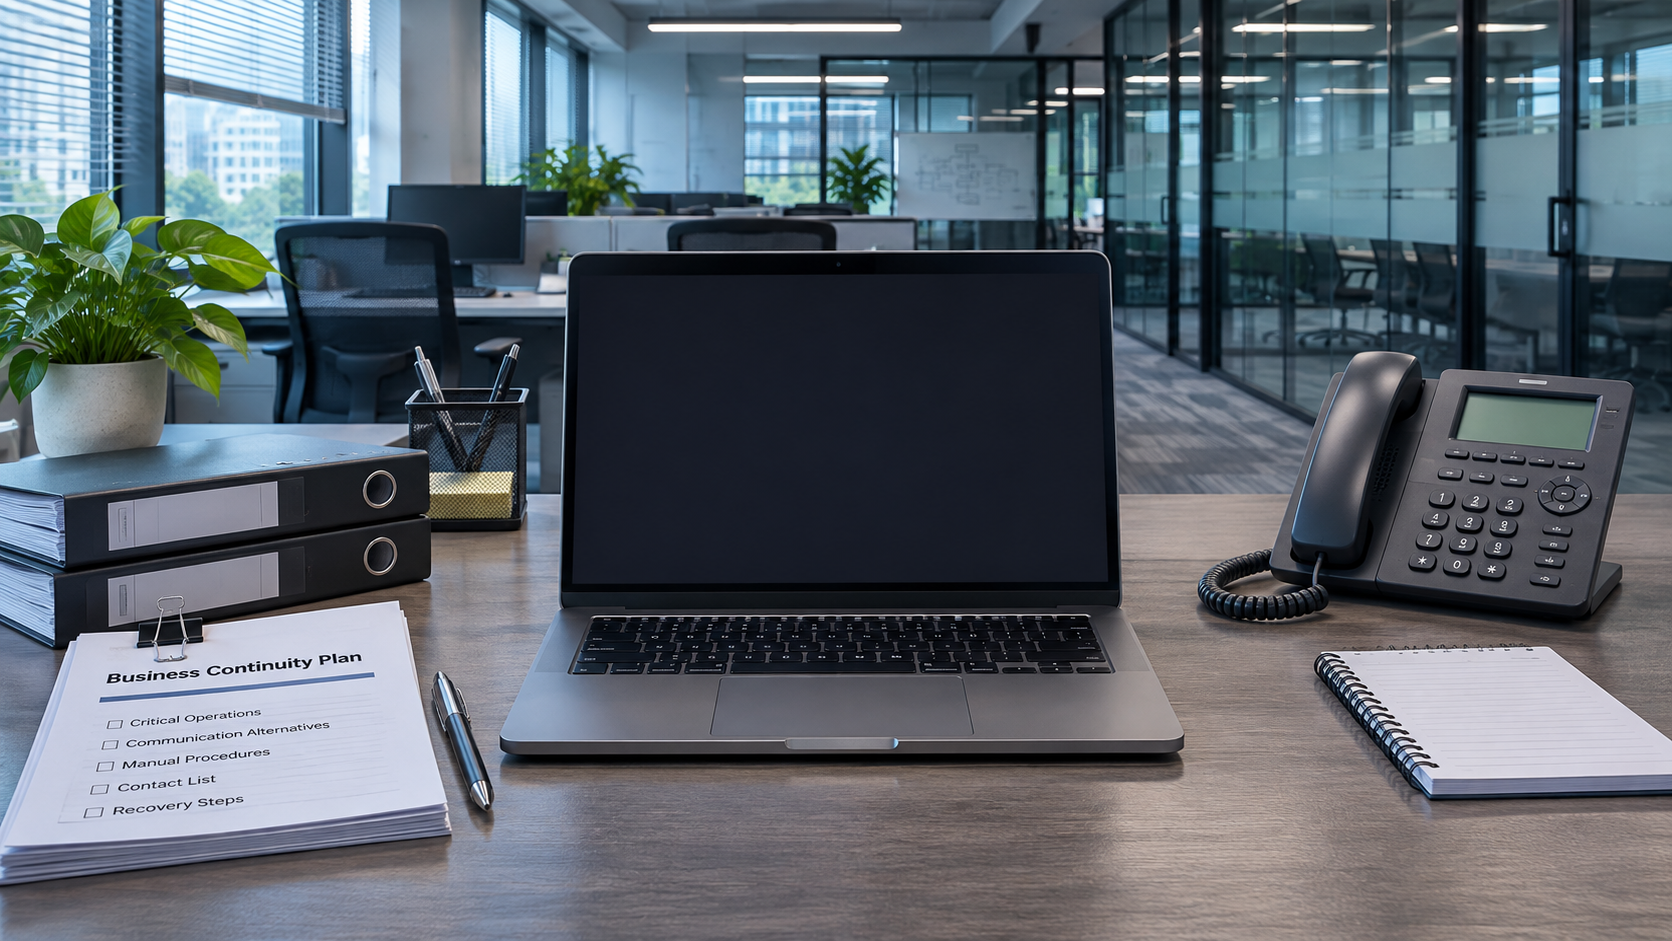
The incident highlights a distinction between having multiple applications and having independent ways to continue working. If several services rely on the same underlying infrastructure, an outage affecting that infrastructure can disrupt them together. The presence of several familiar tools does not by itself establish that one will remain available when another fails.
For organizations assessing their exposure, the issue is therefore not limited to whether a particular application can be reached. It also includes which essential activities depend on that application, whether those activities can proceed through another channel, and how staff would coordinate while normal services are unavailable. The answers will differ between an organization that relies heavily on cloud-based communication and one with workable alternatives for its most time-sensitive tasks.
The present incident does not establish which continuity arrangements affected organizations had in place or how effective those arrangements were. It does, however, provide a concrete reason to examine dependencies across email, collaboration and other connected services together.
Recovery and longer-term questions
The immediate question is how quickly the affected services return to normal operation. Because some repair measures have not yet fully taken effect, recovery may need to be assessed across the individual services rather than treated as a single point in time.
Further public information from Microsoft may clarify the cause, the scope of the disruption and the effectiveness of the remedial measures. Those details would also help organizations assess whether the incident calls for changes to their redundancy and business continuity arrangements. For now, the strongest conclusion is that a prolonged disruption to a shared cloud environment can affect several core functions at once; the extent of any lasting change in cloud architecture remains to be seen.
Deep Dive
Related Intelligence
 Cloud InfrastructureWhy do project managers choose ERP software with built-in compliance tracking for green building projects?Analyst:IT & Security Director
 Cloud InfrastructureHow do barcode scanners improve inventory accuracy on large-scale construction sites with mixed material deliveries?Analyst:IT & Security Director
 Cloud InfrastructureWhat ERP software features help procurement teams track chemical inventory across multiple construction sites?Analyst:IT & Security Director