How cloud native infrastructure architecture shapes platform scalability
Key Takeaways
- When does modular construction reduce a project's total cost?Chief Civil Engineer
- What cloud infrastructure analysis reveals about Singapore latency risksIT & Security Director
- How to verify recycled green building materials meet project standardsChief Civil Engineer
- What to evaluate when comparing cybersecurity analysis providersIT & Security Director
- When does agricultural automation equipment pay off for mid-size farms?Agri-Tech Strategist
- How Tank Design Helps Reduce Oxidation Risks in Edible Oil StorageAgri-Tech Strategist
- How to match heavy duty earthmoving equipment to site conditionsChief Civil Engineer
- When chemical supply solutions reduce the risk of production downtimeLead Materials Scientist
Industry Overview
We do not just publish news; we construct a high-fidelity digital footprint for our partners. By aligning with TNE, enterprises build the essential algorithmic "Trust Signals" required by modern search engines, ensuring they stand out to high-net-worth buyers in an increasingly crowded global digital landscape.
At 09:00, a B2B platform may be processing routine product searches from a few regions. By noon, a procurement event, a seasonal buying cycle, or a supply-chain disruption can bring a surge of requests from distributors, manufacturers, logistics partners, and internal analytics systems at once. The visible experience may be a search page or supplier portal; underneath, it is a test of architecture.
For enterprises operating across global markets, cloud native infrastructure architecture has become a practical measure of whether a digital platform can grow without becoming fragile. It influences how quickly teams release new capabilities, how well systems recover from faults, how safely data crosses regional boundaries, and whether a platform can keep serving users when demand becomes unpredictable.
For technical evaluators, the important question is not whether a vendor uses containers, Kubernetes, or a managed cloud service. Those components matter, but they do not alone create scalability. The deeper question is whether the architecture has been designed so that capacity, failure handling, data flow, security, and deployment practices can evolve together.
Scalability begins with the shape of the system
Traditional enterprise systems often scale by making a central application server larger. This vertical scaling model can work for stable internal workloads, but it becomes restrictive when a platform must support continuous integration, external APIs, real-time data feeds, multilingual content, partner onboarding, and uneven traffic patterns. A single tightly coupled application may have one overloaded function, yet require the entire stack to be expanded or redeployed.
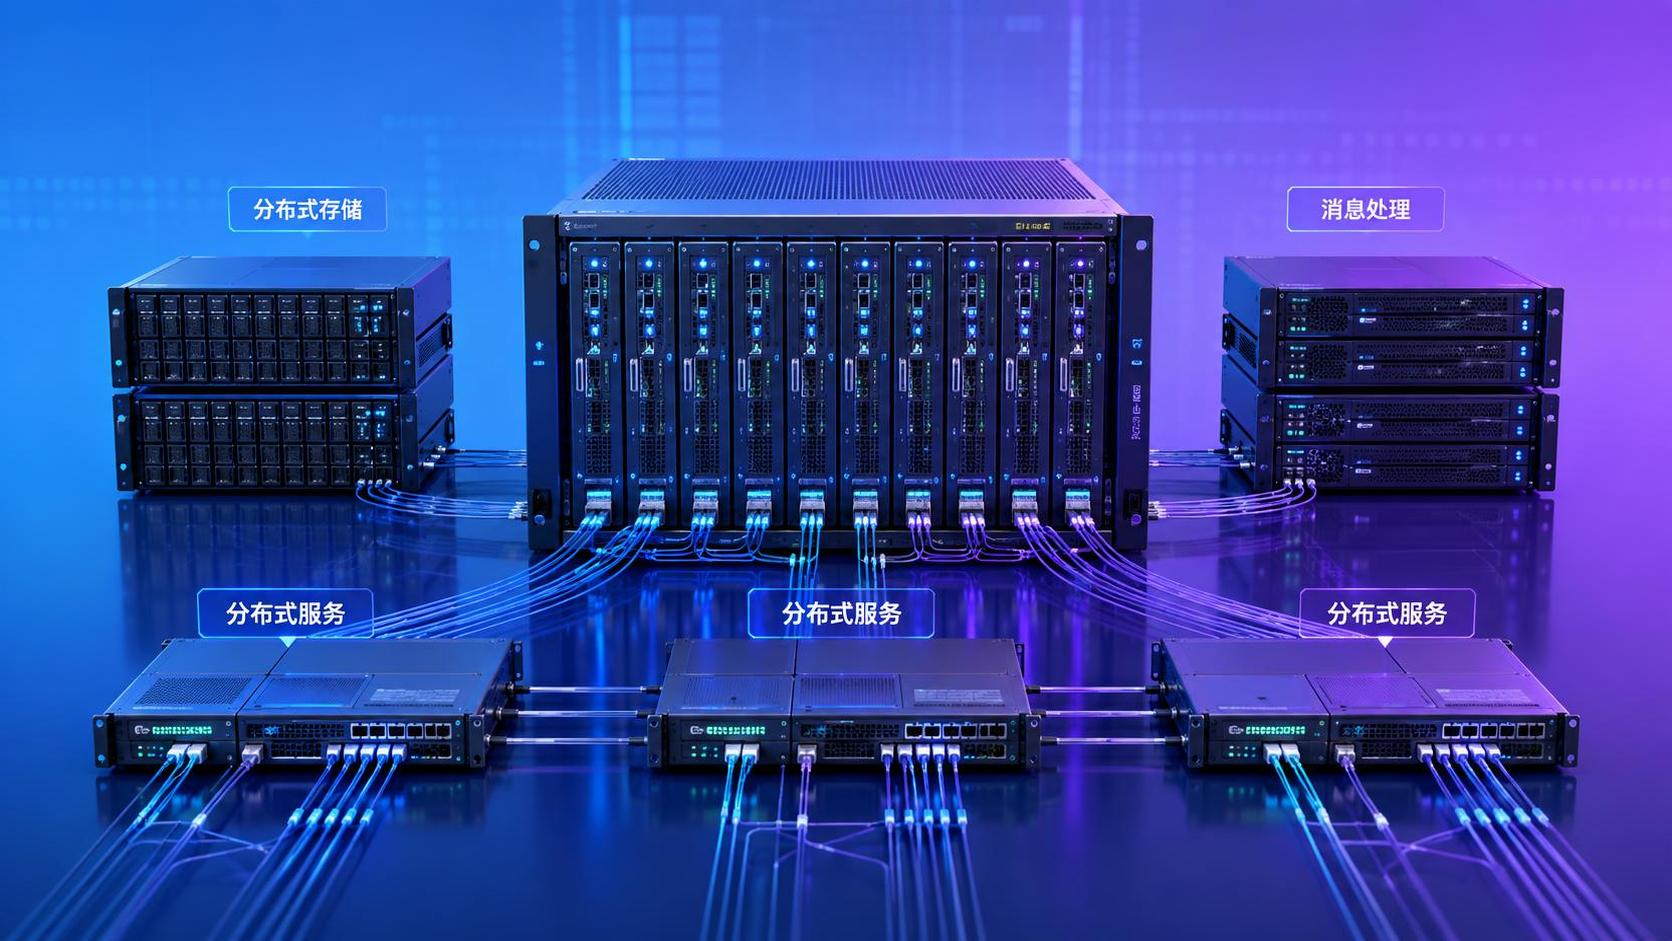
Cloud-native design changes that equation by treating the platform as a collection of independently operable capabilities. An identity service, product-search function, document-processing pipeline, notification engine, market-data workflow, or recommendation module can be deployed and scaled according to its own behavior. The goal is not to break everything into the smallest possible services. It is to establish boundaries that reflect real business and operational needs.
That distinction matters. An overly fragmented microservices environment may introduce more network calls, deployment dependencies, and observability gaps than the organization can realistically manage. Conversely, a well-structured modular application running in containers can provide many cloud-native advantages before a full microservices transition is justified.
Technical teams should therefore assess architecture in terms of independent change and independent scale. If a platform’s search traffic rises sharply, can search components expand without increasing the capacity of billing, content administration, or analytics? If a new compliance workflow is introduced, can it be delivered without placing the core trading experience at risk? Those answers reveal more than an infrastructure diagram.
Elastic compute is only one layer of platform scalability
Autoscaling is often the most visible feature of cloud-native infrastructure architecture. Container orchestration platforms can add or remove application instances based on CPU consumption, memory pressure, queue depth, request rate, or custom business metrics. This is useful, but compute elasticity does not solve every bottleneck.
A platform may add ten times more API instances and still fail if its database cannot accept more writes, a third-party integration is rate-limited, or a shared message broker becomes congested. In global B2B environments, this frequently occurs when catalog updates, pricing requests, inventory synchronization, document uploads, and buyer searches converge on the same data services.
A scalable architecture separates synchronous user interactions from work that can safely happen later. A buyer should not need to wait for image processing, report generation, ERP synchronization, or an external notification before receiving a confirmation that a request has been accepted. Event-driven patterns, message queues, and durable workflows allow the platform to absorb peaks rather than forcing every task into a single request-response cycle.
Queues are not merely performance tools. They are buffers between systems that operate at different speeds and with different reliability profiles. They also make failure handling more deliberate: messages can be retried, routed to a dead-letter process, inspected, and replayed under controlled conditions. For sectors where product specifications, certifications, logistics records, or supplier data must remain traceable, this operational discipline is essential.
Stateful data is where many scalability plans become difficult
Application containers are designed to be replaced. Business data is not. This is why data architecture deserves at least as much scrutiny as the compute layer.
Stateless application services can scale horizontally with relative ease when session information, files, caches, and shared state are externalized. But enterprise platforms usually rely on several data patterns at once: transactional records requiring strong consistency, search indexes optimized for fast retrieval, object storage for technical documents, streams for event processing, and analytical stores for reporting or forecasting.
Attempting to force every workload into one relational database creates an avoidable concentration of risk. At the same time, indiscriminately adopting many specialized databases can create governance problems, unclear ownership, and difficult reconciliation. A mature cloud-native platform makes data choices according to access patterns and business consequences.
- Transactional data needs clear integrity rules, reliable backup, recovery testing, and an understood replication model.
- Search and discovery data may favor denormalized indexes and asynchronous updates to deliver responsive supplier, product, or technical-content queries.
- Event data benefits from durable streams that allow downstream services to react without tightly coupling to the originating system.
- Analytical data should be governed so that reporting workloads do not compete with operational transactions at critical moments.
Data residency adds another layer for multinational operations. A platform may need to serve users close to their location while ensuring certain records remain within specified jurisdictions. The architectural response is not simply “deploy in every region.” Teams need a documented model for where authoritative data resides, what is replicated, how conflicts are resolved, and which services can continue operating during a regional disruption.
Resilience is designed before an outage, not added after one
Scalability and resilience are closely connected, but they are not interchangeable. A system can handle high traffic and still fail badly when a dependency becomes slow, a deployment introduces a defect, or an availability zone experiences an incident.
Cloud-native infrastructure architecture should assume that individual components will fail. The practical response includes health checks, multiple instances, readiness gates, timeouts, circuit breakers, rate limits, and graceful degradation. These mechanisms prevent a localized issue from becoming a platform-wide outage.
Consider a global intelligence platform that enriches company profiles using external data sources. If one external endpoint becomes unavailable, the platform should not necessarily block user access to existing profiles. It may display the last verified information with a freshness indicator, defer enrichment jobs, and alert the operations team. That is a more useful failure mode than allowing one dependency to exhaust all available request threads.
Resilience also depends on deployment strategy. Rolling deployments, canary releases, feature flags, and automated rollback criteria reduce the blast radius of change. For technical evaluators, the key evidence is not a claim that deployments are “zero downtime.” It is whether the team can explain how a risky change is isolated, observed, reversed, and learned from.
Observability turns distributed complexity into operational evidence
As platforms become more distributed, traditional server monitoring becomes insufficient. A dashboard showing that servers are online does not explain why a user’s supplier search took eight seconds, why a document workflow stalled, or why a regional partner cannot complete authentication.
Observability connects signals across the system: metrics show trends, logs provide detailed records, and traces reveal the path of a request through services and dependencies. Together, these signals give operators a way to distinguish between a capacity issue, an application defect, a database delay, and an external service failure.
The most useful observability design begins with user-facing outcomes rather than infrastructure components alone. Examples include search latency, successful API requests, time to publish a product record, percentage of completed onboarding flows, or the age of synchronized inventory data. These service-level indicators help teams decide what “healthy” means in business terms.
For platforms supporting high-value industrial decisions, this visibility has a trust dimension. When users rely on technical specifications, supplier records, material information, or security guidance, silent data failures can be more damaging than obvious downtime. Architecture should make data freshness, ingestion errors, and processing exceptions visible to the teams responsible for quality.
Security must be embedded in the delivery path
Cloud-native environments can accelerate release cycles, but speed without controls creates a growing attack surface. Containers, APIs, infrastructure templates, service identities, and software dependencies all require governance. Security cannot remain a separate review performed shortly before production release.
A sound approach applies security across the software supply chain: source code scanning, dependency checks, image signing, secrets management, least-privilege access, policy enforcement, runtime monitoring, and auditable infrastructure changes. Infrastructure as code is particularly important because it makes network settings, permissions, and environment configuration reviewable and repeatable rather than dependent on manual console changes.
Zero-trust principles are especially relevant where platforms connect internal teams with customers, suppliers, marketplaces, and third-party systems. Each request should be authenticated and authorized according to context, rather than trusted simply because it originates from a particular network segment. This does not mean adding friction everywhere. It means designing identity, access, and service-to-service communication with explicit rules.
What technical evaluators should challenge during assessment
Architecture reviews are often distracted by tool names. Kubernetes, service meshes, serverless functions, and managed databases may all be appropriate, but none is a substitute for operational clarity. A stronger evaluation asks how the architecture behaves under realistic constraints.
- What workloads drive scale? Identify predictable growth, burst traffic, batch processing, partner integrations, and regional demand separately. They may need different scaling strategies.
- Where are the shared dependencies? Map databases, identity providers, caches, message brokers, API gateways, and external services. Shared components are often the true limits on scale.
- How is failure contained? Ask for dependency timeout policies, retry behavior, queue handling, degradation plans, and recovery procedures—not only high-level availability targets.
- How are releases controlled? Review testing environments, deployment automation, rollback mechanisms, approval requirements, and evidence from prior incidents or change reviews.
- How is cost governed? Elastic infrastructure can prevent overprovisioning, but unobserved autoscaling, data transfer, idle environments, and excessive logging can produce unwelcome cost growth.
- Can the organization operate it? The architecture must match the skills, on-call maturity, security model, and ownership structure of the teams running it.
The final point is often underestimated. A sophisticated platform with dozens of services may look impressive in a proposal, yet become difficult to maintain if teams lack clear service ownership or the ability to diagnose distributed incidents. Architectural maturity is as much about operating practices as it is about technology selection.
A measured route to cloud-native scale
Modernization does not have to begin with a dramatic rewrite. Many organizations gain meaningful improvements by containerizing a modular application, automating deployments, externalizing session state, improving telemetry, and moving background work to asynchronous processing. These changes create a foundation for more targeted service decomposition later.
For a global B2B ecosystem, the value of this approach is tangible. Market intelligence, technical content, supplier interactions, and enterprise integrations do not all evolve at the same pace. A flexible architecture lets teams improve one domain without destabilizing another, while maintaining the governance required for trusted decision-making.
TradeNexus Edge operates in an environment where industrial and technology leaders need context as well as speed: from advanced materials and agri-tech to smart construction, e-mobility, and enterprise cybersecurity. In that setting, infrastructure choices shape more than page performance. They influence whether information can be updated reliably, whether new digital services can be introduced responsibly, and whether global users can depend on the platform when conditions change.
Ultimately, cloud-native infrastructure architecture is not defined by a particular vendor stack or fashionable pattern. It is defined by disciplined choices: isolate what must scale independently, protect the data that must remain trustworthy, design for partial failure, observe real user outcomes, and make security part of every delivery decision. When those principles are present, scalability becomes a capability the organization can repeatedly use—not a temporary response to its next surge in demand.
Deep Dive
Related Intelligence
 Cloud InfrastructureWhy do project managers choose ERP software with built-in compliance tracking for green building projects?Analyst:IT & Security Director
 Cloud InfrastructureHow do barcode scanners improve inventory accuracy on large-scale construction sites with mixed material deliveries?Analyst:IT & Security Director
 Cloud InfrastructureWhat ERP software features help procurement teams track chemical inventory across multiple construction sites?Analyst:IT & Security Director